From "how much" to "which one"
Last chapter predicted a quantity. This one chooses a category: spam or not, cat or dog, which is Chapter 1's classification. The work is picking the function that squashes a score into a probability, and knowing why it is that one.
Our straight-line score can roam from minus a million to plus a million; a probability must stay between 0 and 1.
| Stage | Job |
|---|---|
| Weighted score | Combine the inputs. |
| Sigmoid | An S-shaped curve squashes any score into a probability between 0 and 1; we will build it below. |
| Threshold | A cutoff, such as 0.5: above it we vote class 1, below it class 0. |
A score that roams too far
We keep Chapter 3's weighted sum and intercept $b$, now called the bias. The raw score is the logit $z$:

In words: multiply each input by its weight, add them all up (that is the dot product from Chapter 2), then add the bias $b$. With one input, that center dot is the ordinary multiplication we used last chapter; with several, it is Chapter 2's dot product. It is the same recipe in one slot or many. For a single input feature this is a line; for several inputs it is a dot product plus a number. In this formula $\mathbf{w}$ is the vector of weights, $\mathbf{x}$ the input, and $b$ a single number.
The exponential $e^z$ supplies the ingredient we need: it is always positive and grows by multiplying. The constant $e$ is about $2.718$.
| Exponent $z$ | $e^z$ |
|---|---|
| $-2$ | $0.14$ |
| $-1$ | $0.37$ |
| $0$ | $1$ |
| $1$ | $2.72$ |
| $2$ | $7.39$ |
A negative exponent means reciprocal: $e^{-2}=1/e^2=1/7.39\approx0.14$.
Very negative scores map near 0, very positive scores near 1, and zero to 0.5. For the slow build of $e^x$ and its partner $\ln x$, see Functions and Curves.
The sigmoid, in full

The sigmoid hugs 0 and 1 without reaching either; $\sigma(z)$ reads “sigma of z.”
$$\sigma(z) = \frac{1}{1 + e^{-z}}$$In words: take $e$ to the minus $z$, add 1, and divide 1 by the result. Because $e^{-z}$ is always positive, the bottom is always bigger than 1, so the whole fraction always lands between 0 and 1.
| Score | $e^{-z}$ | $1/(1+e^{-z})$ |
|---|---|---|
| $-2$ | $7.39$ | $0.12$ |
| $0$ | $1$ | $0.50$ |
| $2$ | $0.14$ | $0.88$ |
At the center, $\sigma(0)=1/(1+1)=0.5$; for a positive score:
$$\sigma(2) = \frac{1}{1 + e^{-2}} \approx \frac{1}{1.14} \approx 0.88$$In words: $e^{-2}$ is about $0.14$, so the bottom is about $1.14$, and 1 divided by $1.14$ is about $0.88$, a confident vote for class 1.
The mirror case is $\sigma(-2)=1/(1+e^2)=1/(1+7.39)\approx0.12$. Thus $\sigma(2)+\sigma(-2)\approx1$; generally $\sigma(-z)=1-\sigma(z)$. The decision boundary is where the probability crosses 0.5 and the vote switches.
Worked example: pass or fail from hours studied
Suppose we predict pass (1) or fail (0) from hours studied, and training has set the model to $\sigma\bigl(2(x - 3)\bigr)$, so the boundary sits at $x = 3$ hours. The same three checkpoints reappear as real predictions:
| hours $x$ | logit $z = 2(x-3)$ | probability $\sigma(z)$ | verdict |
|---|---|---|---|
| $2$ | $-2$ | $\approx 0.12$ | likely fail |
| $3$ | $0$ | $0.50$ | a coin flip |
| $4$ | $2$ | $\approx 0.88$ | likely pass |
The sigmoid's three checkpoints, $0.12$, $0.50$, $0.88$, are the model's three predictions.
Fitting $\mathbf{w}$ and $b$ so $\sigma(\mathbf{w}\cdot\mathbf{x}+b)$ matches the 0/1 labels is logistic regression.
Why this curve
Three properties make the sigmoid the right squashing function here.
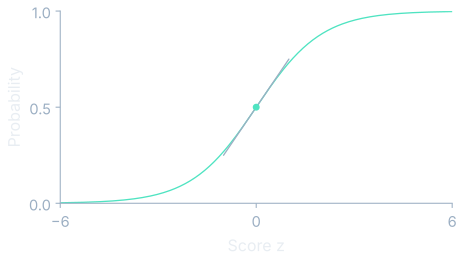
A saturating detector has the same shape. At the bottom the input is lost in the noise floor and almost nothing comes out. Through the middle the response rises sharply. At the top the amplifier is fully driven and pushing harder changes little. A real receiver’s response follows a different curve, but it has those same three regions: floor, responsive middle, ceiling.
| Property | What it means |
|---|---|
| Range | Strictly between 0 and 1 |
| Smooth slope | No jumps or corners |
| Symmetry | Opposite scores sum to 1 |
| Property | Why it holds |
|---|---|
| Range | $e^{-z}>0$ makes the denominator bigger than 1; finite scores give outputs strictly between 0 and 1. |
| Smoothness | A hard step has zero slope off its jump and no defined slope at the jump. Gradient descent needs slopes. |
| Monotonicity and symmetry | Bigger scores give bigger probabilities; reversing the score exchanges the classes. |
In words: the slope of the sigmoid at any point is its own output times one-minus-its-output. That is largest at the center: at $z = 0$, where $\sigma = 0.5$, the slope is $0.5 \times 0.5 = 0.25$. It shrinks toward zero at both tails, where $\sigma$ is near 0 or near 1. The lower panel of the sigmoid anatomy figure shows this hump-shaped slope aligned right under the S-curve.
Check the center by rise-over-run: from $z=-0.2$ to $+0.2$, the output rises from about $0.45$ to $0.55$. That is $0.10/0.4\approx0.25$, matching $0.5\times0.5$.
- Left tailOutput near 0; slope near 0.
- CenterOutput $0.5$; slope $0.25$.
- Right tailOutput near 1; slope near 0.
Near-flat tails pass back tiny slopes; multiplying these through many layers leaves early weights barely learning. This is the vanishing gradient problem.
Drawing the boundary in two dimensions
| Layer job | Sigmoid behavior | Consequence |
|---|---|---|
| Binary output | A probability between 0 and 1 | Fits the output we need |
| Hidden layer center | Slope at most $0.25$ | Each layer shrinks the signal |
| Hidden layer tails | Slope near zero | Early weights barely learn |
With two features, $z=\mathbf{w}\cdot\mathbf{x}+b$ is zero on a straight line: the boundary where $\sigma=0.5$. Above that probability we vote class 1; below it, class 0.

Let $\mathbf{w}=[1,1]$ and $b=-3$:
$$z = \mathbf{w} \cdot \mathbf{x} + b = 1 \cdot x_1 + 1 \cdot x_2 - 3, \qquad \text{boundary: } x_1 + x_2 = 3$$In words: add the two features, subtract 3, and that is the score; the boundary is the set of points where the two features add up to exactly 3.
| Input | Score | Probability; class |
|---|---|---|
| $[1,1]$ | $1+1-3=-1$ | $1/(1+2.72)\approx0.27$; class 0 |
| $[2,3]$ | $2+3-3=2$ | $0.88$; class 1 |
The weight vector points perpendicular to the line toward increasing class-1 confidence. Larger weights sharpen the transition; smaller weights soften it. Training moves and tilts the boundary.
| Change | Effect on boundary | Effect on transition |
|---|---|---|
| Bias | Slides the line | Shifts the midpoint |
| Relative weights | Tilts the line | Changes which inputs count |
| Positive scale on weights and bias | Same zero-score line | Larger scale sharpens it |
We use gradient descent with cross-entropy loss, which penalizes confident wrong probabilities much more heavily than squared error does on 0/1 labels. Measuring Wrongness develops that loss; the model/loss/descent loop is unchanged.
The family of squashing functions
These activation functions bend a neuron's weighted sum. Choose one by the layer's job.

| Function | Rule | Range | Where used |
|---|---|---|---|
| Sigmoid | $1/(1+e^{-z})$ | 0 to 1 | Binary output |
| tanh | $2\sigma(2z)-1$ | −1 to 1 | Zero-centered recurrent states; still saturates |
| ReLU | $\max(0,z)$ | 0 upward | Cheap hidden units; positive slope 1, negative slope 0 can kill units |
| Leaky ReLU | $\max(az,z)$; $a$ is the negative-side slope, $0<a<1$ | Unbounded | Hidden units; lets negative units recover |
| GELU | A smooth, slightly curved version of ReLU: it eases through the corner at zero rather than kinking sharply. | Slightly negative upward | Transformer hidden units; eases ReLU's corner |
In words: pass positive scores straight through unchanged, and clamp every negative score to zero. That is the entire function.
Softmax: more than two options
Ten digits, a thousand objects, or fifty thousand next words need a distribution, not a single probability. The softmax turns a score vector $\mathbf{z}$ into probabilities; $i$ names one option and $j$ runs over all options.

In words: the probability of option $i$ is $e$-to-its-score divided by the sum of $e$-to-every-score. The bottom is the same total for all options, so each option gets its exponentiated score as a share of the whole.
Worked example: three scores become a distribution
| Option | Score | Positive value |
|---|---|---|
| A | $2$ | $e^2\approx7.39$ |
| B | $1$ | $e^1\approx2.72$ |
| C | $0$ | $e^0=1$ |
Take three options with scores $\mathbf{z} = [2, 1, 0]$. Exponentiate each: $e^2 \approx 7.39$, $e^1 \approx 2.72$, $e^0 = 1$. The total is $7.39 + 2.72 + 1 = 11.11$. Now divide each by that total:
$$\mathbf{z} = [2, 1, 0] \;\rightarrow\; \left[\tfrac{7.39}{11.11},\, \tfrac{2.72}{11.11},\, \tfrac{1}{11.11}\right] \approx [0.665,\, 0.245,\, 0.090]$$In words: raise $e$ to each score to make every value positive, add those three to get $11.11$, then divide each by that total. The scores $2, 1, 0$ became a probability distribution $0.665, 0.245, 0.090$ that sums to 1.
| Option | Divide by total | Probability |
|---|---|---|
| A | $7.39/11.11$ | $0.665$ |
| B | $2.72/11.11$ | $0.245$ |
| C | $1/11.11$ | $0.090$ |
With two scores, the first probability is $e^{z_1}/(e^{z_1}+e^{z_2})$. Divide top and bottom by $e^{z_1}$: $1/(1+e^{z_2-z_1})$. That is the sigmoid of the score gap, so sigmoid is softmax's two-class case. A language model uses the same operation over its possible next words.
See it move
Watch the score become a probability and the threshold become a boundary.
Drag the grapher's input $z$, switch functions, and turn on its slope overlay.
- Sigmoid: find $0.12$, $0.50$, $0.88$; the boundary is $z=0$.
- Slope: drag far right and watch it approach zero.
- ReLU: confirm slope 1 for positive $z$, 0 for negative $z$.
- Softmax: scores $[2,1,0]$ give $0.665/0.245/0.090$; equal scores give equal bars.
Where you'll meet this
| Where | What it looks like | Chapter link |
|---|---|---|
| Neuron | Weighted sum $z=\mathbf{w}\cdot\mathbf{x}+b$, then a squash | The neuron |
| Hidden layers | ReLU or GELU preserves useful gradients | Teaching the network |
| Language output | Softmax assigns belief to possible next words | Measuring wrongness |
What you now know
- A sigmoid turns any finite score into a probability strictly between 0 and 1.
- Its smooth, increasing, symmetric curve has nearly flat tails that can stall deep learning.
- Logistic regression learns a straight boundary with cross-entropy and gradient descent.
- Hidden activations support learning; output activations match the question.
- Softmax distributes belief across options; it does not choose an answer.
Where we’re headed. We have a weighted sum and a squash. Next we combine them into one neuron, then stack neurons to learn curved boundaries.