Sorters and makers
The line-fitter predicted prices, the classifier chose categories, and our small network learned inside from outside a curved region. This chapter builds a machine that makes a new picture. How can arithmetic produce a face nobody photographed?

| Earlier idea | Used here to… |
|---|---|
| Training | Adjust a model to examples |
| Probability | Describe and sample outcomes |
| Neural network | Represent a flexible learned rule |
A discriminative model predicts a label or value from an input. A generative model learns the distribution of the data itself so it can produce new samples; write input $x$ and answer $y$:
$$p(y \mid x) \qquad \text{vs.} \qquad p(x)$$In words: a sorter models the probability of a label $y$ given an input $x$: "shown this photo, how likely is 'cat'?" A maker models $p(x)$, the probability of the input itself: "how likely is this arrangement of pixels to be a real photo at all?" Learn that second one and you can grade any image for realness, and generate new ones that score high.
| Family | Learned mechanism | New sample comes from… |
|---|---|---|
| VAE | Compression and reconstruction | Decoding a sampled latent point |
| GAN | A generator and a judge | Running the generator |
| Diffusion | Noise prediction | Repeatedly denoising fresh static |
We will compare three ways to learn that distribution: VAEs, GANs, and diffusion.
Learn the distribution, then sample
To make new data, learn its distribution, then sample. In the math toolkit, a distribution spread belief across outcomes: common things get more, rare things less.
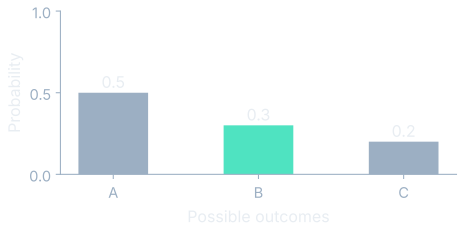
We write that draw with a tilde:
$$x \sim p(x)$$In words: read the little tilde $\sim$ as "drawn from." We pick an $x$ at random, according to the distribution $p(x)$ rather than evenly, so common things come up often and rare things almost never. An LLM does the same thing when it samples a next token from a probability distribution (the sister site's prediction game). Here the "token" is an entire image.
| Outcome | Probability | One possible draw |
|---|---|---|
| A | $0.5$ | Not selected |
| B | $0.3$ | Selected |
| C | $0.2$ | Not selected |
For faces, two eyes above a nose are common; random static rarely resembles a face. Learning that pattern across millions of pixel dimensions is difficult: plausible images occupy a thin, curved region, not a table we can fill by hand.
We can also condition sampling, steering it with extra information: a smiling face, a cat in Van Gogh's style, or a harbor at dusk from the air.
VAEs: a map you can wander
PCA compressed many features into a few useful directions. A variational autoencoder (VAE) turns compression and reconstruction into a generator using two trainable networks.

The encoder compresses an image into a latent code, which is a small vector on a compact map. The decoder rebuilds the image from that code. Train both so encode-then-decode approximately restores the input.
$$x \;\xrightarrow{\text{encode}}\; z \;\xrightarrow{\text{decode}}\; \hat{x}$$In words: the image $x$ is encoded down to the latent code $z$, then decoded back up to $\hat{x}$, read "x-hat," the model's rebuilt version of the image. The hat means "the model's version," the same convention we used for the prediction $\hat{y}$ in earlier chapters; here the model is rebuilding an input rather than guessing a label.
| Latent point in the illustration | Decoder result |
|---|---|
| $(0.3,-0.8)$ | Original reconstruction |
| $(0.9,-0.8)$ | Wider smile |
| $(-0.5,0.4)$ | A new face |
A second training pressure keeps the latent codes near a smooth distribution around the origin, so nearby samples tend to decode plausibly. In our illustration, a face has code $z=(0.3,-0.8)$. Moving its first coordinate from $0.3$ toward $0.9$ widens the smile; a new point $z=(-0.5,0.4)$ decodes to a new face. These are illustrative coordinates, not universal smile controls.
That is how a VAE generates: sample a latent point and decode it. VAEs are stable to train and give an organized map, though averaging over possible reconstructions can produce blurry outputs.
GANs: the forger and the detective
A generative adversarial network (GAN) trains two networks against each other.

The generator is the forger: random numbers go in, a fake image comes out. The discriminator is the detective: it sees real images mixed with fakes and learns which is which. Both use gradient descent, with opposing goals.
- Detect: early fakes are easy to recognize.
- Improve: the discriminator’s error signal teaches the generator what gave it away.
- Repeat: better fakes demand a sharper discriminator, which supplies harder feedback.
- Generate: keep the trained generator; generation no longer needs the discriminator.
In the ideal balanced outcome, the detective can do no better than a coin flip, outputting about $0.5$. That is the goal, not a guarantee that every training run reaches it.
GAN images can be sharp because blur gives the detective a clue. But the contest is delicate: in mode collapse, the generator repeats one successful image or a narrow set instead of covering the distribution; the players can also keep chasing each other without settling.
Diffusion: learning to un-blur static
Teach a network to predict noise, then use it repeatedly to turn fresh static into an image.

Worked example: un-noising one pixel
The clean pixel value is $x = 2.0$. This step's noise happened to be $+0.8$, so the noisy pixel is $2.8$:
$$x_{\text{noisy}} = x_{\text{clean}} + \text{noise} \;=\; 2.0 + 0.8 = 2.8$$In words: the noisy pixel is the clean pixel plus the noise that got added, so clean $2.0$ plus noise $0.8$ makes the noisy value $2.8$.
- CleanPixel value $2.0$.
- Noisy$2.0+0.8=2.8$.
- Denoised$2.8-0.8=2.0$.
The network is shown only the $2.8$ and predicts the noise: $+0.8$. Subtract that guess, and the clean pixel is recovered:
$$x_{\text{clean}} = x_{\text{noisy}} - \text{predicted noise} \;=\; 2.8 - 0.8 = 2.0$$In words: the clean pixel is the noisy pixel minus the noise the network predicted, so noisy $2.8$ minus predicted $0.8$ gives back the clean $2.0$. A real model does this for every one of a million pixels at once, and it never sees the clean answer at generation time. It only ever predicts the noise.
This additive pixel example isolates the arithmetic; a full sampler also uses a noise schedule and scaling. Repeating small steps, a few hundred of them in this illustration, allows gradual refinement without the GAN's adversarial contest.
- Start clean: choose a training image.
- Add noise: gradually obscure it until it resembles static.
- Learn: use noisy examples and their known noise to train a predictor.
- Start fresh: draw new random static for generation.
- Denoise: repeatedly apply the trained predictor, building a new image.
For text-to-image, encode “a red bicycle on the moon” into an embedding and supply it at every denoising step to steer the result toward the prompt. Meaning as Direction explains the text vectors. Conditioning guides a sample; it does not guarantee an exact picture.
How AI Makes Images gives the full derivation: noise schedules, prediction, compression, and text guidance.
Choosing a generator
Choose by the kind of control and the training tradeoff the task needs. All three families share one aim, learning the distribution and then sampling from it, and reach it by different routes: a smooth latent map, an adversarial contest, or repeated refinement.
| Family | Useful property | Tradeoff |
|---|---|---|
| VAE | A compact map to sample and explore | Stable training; reconstructions can be soft. |
| GAN | Sharp samples in a focused domain | A delicate contest can become unstable or collapse. |
| Diffusion | Repeated, controllable denoising | Many small generation steps instead of one pass. |
Where you'll meet this
| Where | What it looks like | Chapter link |
|---|---|---|
| Text-to-image | A sentence embedding steers denoising | Meaning as Direction |
| Speech, music, missing data, protein structures, drug candidates | Learn plausible data and sample or fill gaps | Distribution and sampling |
| Language models | Sample the next token from a learned distribution | The prediction game |
| Useful assistants | Feedback steers behavior beyond matching examples | Learning by doing |
What you now know
- Generative models learn data distributions and draw new samples from them.
- The tilde in $x\sim p(x)$ means “drawn from.”
- VAEs sample a compact latent map and decode its points.
- GANs train a generator against a discriminator, then keep the generator.
- Diffusion repeatedly predicts noise to build an image from fresh static.
- Text embeddings condition generation, while learned patterns can include biases and convincing falsehoods.
Where we’re headed. Matching examples does not establish that an answer is helpful or an action safe. These models inherit patterns and biases, and can invent convincing falsehoods. Next, learning by doing uses rewards and penalties to shape behavior: playing Go, controlling robots, or refining an assistant.