Why a picture breaks a plain network
A photo is a grid of numbers: one brightness per grayscale pixel, three channel values per color pixel. Could we feed that grid into the plain stack from the neuron and ask “cat or dog?” We could, but the wiring would ignore useful structure and require many weights.

Flatten a $100\times100$ grayscale image into a list and it has $10{,}000$ inputs. Connect each to $10{,}000$ hidden neurons and the first layer needs $10{,}000\times10{,}000=100$ million weights. That is the matrix-times-vector count, before any later layers.
| Dense first layer | Cost |
|---|---|
| $100\times100$ grayscale image | $10{,}000$ input values |
| $10{,}000$ hidden neurons | $100$ million input-to-neuron weights |
The parameter count belongs to this particular fully connected layer, not to images in general. More pixels mean more inputs, and more hidden neurons mean more destinations for those inputs. Every pair gets a separate weight. A CNN changes those connections before training begins, so we do not have to learn from examples that neighboring pixels often form the same edge.
Flattening also stops expressing the grid’s neighborhood directly. Vertically adjacent pixels become far apart in the list, while the end of one row sits beside the start of the next. Their values are retained, so the image can be reconstructed if we know the layout; what a plain dense layer lacks is wiring that treats nearby pixels as related.
| Plain dense wiring | Convolution wiring |
|---|---|
| Every output reads every pixel | Each output reads a local patch |
| Separate weights at each output | The same detector weights at every position |
Instead, slide a small detector over local patches and reuse its weights everywhere. That operation is convolution; a network built around these filters is a convolutional neural network, or CNN. We will calculate one detector and try it.
| Wiring | Local patches? | Shared weights? |
|---|---|---|
| Dense layer | No | No |
| Separate local detectors | Yes | No |
| Convolution | Yes | Yes |
Both choices earn their place. Local patches preserve the neighborhood we want the model to use, and reuse keeps the number of learned weights small. Restricting attention to a patch alone would not make the weights shared; we could still give every patch its own separate detector. Convolution does both.
Sliding a filter across the picture
Our $5\times5$ image has identical rows $[1,1,1,0,0]$: bright on the left, dark on the right. The vertical edge lies between columns three and four.
| Position in a filter row | Weight | Purpose |
|---|---|---|
| Left | $1$ | Add brightness |
| Middle | $0$ | Ignore brightness |
| Right | $-1$ | Subtract brightness |
The weights $1,0,-1$ were chosen to compare left with right. The zero ignores the middle column, and the negative weight subtracts the right column instead of treating all brightness as evidence. A uniform bright patch therefore cancels. Reversing the contrast would reverse the signed response; this detector is directional, not a general test for every kind of edge.

A filter, also called a kernel, is a grid of weights. Our $3\times3$ filter $\mathbf{K}$ finds that edge:
$$\mathbf{K} = \begin{bmatrix} 1 & 0 & -1 \\ 1 & 0 & -1 \\ 1 & 0 & -1 \end{bmatrix}$$In words: add the patch’s left column and subtract its right column; matching sides cancel. These nine weights form a local weighted sum like the one inside a neuron.
| Column | Role |
|---|---|
| Left | Add brightness |
| Middle | Ignore |
| Right | Subtract brightness |
Worked example: one edge response
Place it over the edge-straddling patch with three rows $[1,1,0]$. Matching-cell multiplication and addition is the dot product arranged in a square. Call the middle output cell $S_{1,1}$, counting rows and columns from zero:
$$\begin{aligned} S_{1,1} &= \big[(1)(1)+(1)(0)+(0)(-1)\big] \\ &\quad + \big[(1)(1)+(1)(0)+(0)(-1)\big] \\ &\quad + \big[(1)(1)+(1)(0)+(0)(-1)\big] \\ &= 1 + 1 + 1 = 3 \end{aligned}$$In words: multiply matching pixels and weights, then sum; each of three identical rows contributes 1, giving 3.
| Row totals | Patch total |
|---|---|
| $1+1+1$ | $3$ |
- Place: cover three rows and three columns.
- Multiply and sum: compute one raw response.
- Move: shift one pixel and use the identical weights.
Worked example: the complete feature map
Slide one position at a time wherever the filter fits. Each sum fills a feature map:
$$\begin{bmatrix} 0 & 3 & 3 \\ 0 & 3 & 3 \\ 0 & 3 & 3 \end{bmatrix}$$In words: edge-straddling patches give $3$; flat-bright patches give $0$, since each all-ones row computes $(1)(1)+(1)(0)+(1)(-1)=0$. Three such rows still sum to zero.
| Window columns | Response |
|---|---|
| 1–3: flat | $0$ |
| 2–4 or 3–5: edge | $3$ |
The map shrinks because the filter must fit inside the image; adding border zeros can preserve its size. A CNN then applies an activation, usually ReLU: keep positive values, replace negatives with zero. Our displayed maps are raw sums; here ReLU leaves them unchanged.
A filter is a feature detector
| Raw response | After ReLU | What remains |
|---|---|---|
| $-3$ | $0$ | Negative response removed |
| $0$ | $0$ | No response |
| $3$ | $3$ | Positive response preserved |
A filter detects a particular pattern. On the same image, compare a horizontal-edge filter $\mathbf{K}_{\text{horizontal}}$:
The two filters see identical pixels. Only their weight arrangements differ, which lets us isolate what “feature” means here: a particular measurement of the same patch. A zero horizontal response does not say the image is empty or unimportant. It says this detector found no top-versus-bottom contrast. Another detector can give a strong response at the same location.

In words: subtract the bottom row from the top; our image’s rows match, so every output is $0$. The horizontal feature map is all zeros.
The weights are the pattern the filter detects. We hand-chose $[[1,0,-1],\dots]$ to make arithmetic readable. A learned CNN starts with random filter weights and adjusts them through gradient descent. No edge labels are required: filters change when doing so helps the network’s training objective.
| Filter | Map on this image |
|---|---|
| Vertical contrast | Rows of $[0,3,3]$ |
| Horizontal contrast | All zeros |
Keep the stack’s two axes of variation separate. Moving across a map changes where we look; moving between maps changes which pattern we measure. A later layer can combine responses across these maps as well as across nearby positions. Its input is already a description of local patterns, so it can build a richer description from them.
| Move through… | What changes | What is shared |
|---|---|---|
| One feature map | Image position | Filter weights |
| Different feature maps | The filter | Input image |
| Later layers | Combined patterns | Weights within each new map |
A layer can use $64$ filters on the same image, producing $64$ maps. Different maps respond to different patterns and retain where those responses occur. That is what “learning features” means: the representation changes from raw pixel values into measurements that help the task.
Sharing the weights
| Layer depth | Evidence available | Possible use |
|---|---|---|
| Early | Local brightness contrasts | Edges |
| Middle | Combinations of edges | Shapes and textures |
| Later | Combinations across larger regions | Evidence for objects |
Now count the savings. Turn our $5\times5$ image, $25$ inputs, into a $3\times3$ map, $9$ outputs. A dense layer connects every input to every output; one convolution slides a single nine-weight filter. We count weights here, omitting biases:
The three snapshots use different patches from the same image. They are three evaluations of one filter. If training changes the top-left weight in the single weight box, that change applies at every placement, and each output still has its own value because each placement multiplies the shared weights by different input pixels.
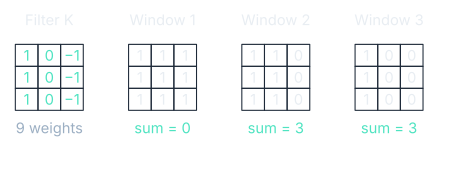
In words: dense wiring needs $225$ weights; the convolution needs nine, reused at all nine positions. A larger image adds positions to evaluate, while the same single-channel filter still has nine weights.
Weight sharing is that reuse. A vertical edge has the same local pattern at the top-left or bottom-right, so one learned detector should work in both places. Sharing also means every training location helps adjust the same weights, rather than teaching separate detectors for separate locations.
| Change | What follows |
|---|---|
| Move the window | Read different pixels with the same weights |
| Train one filter weight | Every position uses that updated weight |
Fewer weights does not mean free computation. A larger image supplies more windows, so the detector must be evaluated more times even though its parameter count stays fixed. Likewise, using more filters adds both weights and output maps. The saving concerns shared parameters; the image size still affects the work of making a prediction.
Translation equivariance means shifting the input shifts the response map correspondingly, away from boundary effects. It does not mean every shifted image gives an identical final classification. Here we share weights across space; the next chapter shares them across time.
| Equivariance | Invariance |
|---|---|
| Move the input; the response moves | Move the input; the output stays unchanged |
Pooling, and what depth adds
Pooling shrinks a feature map by summarizing small blocks. Max pooling keeps the strongest response from each block; our example uses non-overlapping $2\times2$ blocks:

Worked example: four pooled maxima
$$\text{max-pool} \begin{bmatrix} 0 & 3 & 1 & 0 \\ 2 & 3 & 0 & 1 \\ 0 & 0 & 4 & 2 \\ 1 & 0 & 1 & 3 \end{bmatrix} = \begin{bmatrix} 3 & 1 \\ 1 & 4 \end{bmatrix}$$In words: keep the maximum of each block: $3$ at top-left, $1$ at top-right, $1$ at bottom-left, and $4$ at bottom-right. Each side halves, leaving a quarter as many values.
| Block | Values | Maximum |
|---|---|---|
| Top-left | $0,3,2,3$ | $3$ |
| Top-right | $1,0,0,1$ | $1$ |
| Bottom-left | $0,0,1,0$ | $1$ |
| Bottom-right | $4,2,1,3$ | $4$ |
Pooling reduces later computation and can add tolerance to small shifts within a block. It discards exactly where the strongest response occurred. For recognizing an object that tradeoff can help; for locating a boundary precisely, the discarded position may matter.
- Convolve: measure local patterns.
- Activate: apply ReLU to each response.
- Pool when useful: summarize nearby responses.
- Repeat: later filters combine earlier features.
A typical CNN combines convolution, activation, and occasional pooling. Early features can describe edges; later layers combine them into corners, textures, parts, and objects. This is the depth argument: later units reuse earlier computations instead of deriving everything directly from raw pixels.
A deeper unit does not reach directly into every raw pixel. It reads earlier units, which read earlier units in turn, and following those dependencies backward reveals the original region that can influence it. That is why even small filters can collect evidence spread across an object. The edge-to-part stages are the intuition; no learned filter is guaranteed a neat human label.

A first-layer unit sees a $3\times3$ patch. A later unit sees a patch of earlier responses, each already depending on several pixels. Its receptive field, the region of the original image that can affect it, grows with depth.
| Keep | Discard |
|---|---|
| Largest response in each block | Other response values and the winner’s exact position |
See it move
Watch the $3\times3$ filter cross our $5\times5$ image: each dot product fills one feature-map cell, $0$ on the flat and $3$ on the edge. Additional filters supply additional maps, and later layers combine responses.
The playground lets you move a window over the image, inspect its nine multiply-adds, and edit the filter weights. Changing a weight redraws every output position, so it also demonstrates sharing.
When you edit a filter, compare the highlighted patch calculation with the whole map. The first tells you why one value changed, the second shows the effect of using those weights everywhere. If a new pattern fails to appear, check whether the detector’s shape matches it before assuming the arithmetic is wrong.
Why $1/9$ for blur? There are nine pixels under the filter, so nine equal weights of $1/9$ sum to 1 and produce their average. A constant patch stays constant instead of becoming nine times brighter. The edge filter’s weights sum to zero instead, so it removes a constant background and responds to differences across the patch.
Where you'll meet this
| Where | What it looks like | Chapter link |
|---|---|---|
| Images and scans | Local features help recognize digits, objects, or scan patterns | Building features |
| Sound spectrograms | Nearby time-frequency cells form a grid | Sequences |
| Vision transformers | Attention mixes information between image patches | Attention |
| Contact networks | Neighbors lie on arbitrary graphs instead of a pixel grid | Graph networks |
What you now know
- Convolution preserves local grid structure and shares a small filter across positions.
- Each feature-map value is a dot product; our edge example produces $0$ or $3$.
- Training learns filters; multiple filters produce multiple maps.
- Translation equivariance moves the response with the input.
- Pooling trades location detail for smaller maps and some shift tolerance.
- Depth combines features and expands receptive fields.
Where we’re headed. Images share structure across space. A sentence instead unfolds in order: “the dog chased the cat” and “the cat chased the dog” use the same words differently. Remembering machines shares weights across time and asks how a network keeps what came before.